Agent Runtime Setup
Prepare your cluster once, and every agent can get a dedicated runtime. Each run becomes a pod with its own persistent volume, created by the Agent Sandbox controller.
You install three things:
- The controller and its custom resources.
- A storage class with dynamic volume provisioning.
- Archestra's access to the cluster.
Cluster Prerequisites
Your cluster needs Linux nodes compatible with the runtime images, a storage class with dynamic volume provisioning, and the Helm chart's runtime permissions in every execution namespace. Allow outbound access to the image registry, DNS, and Archestra's API, proxy, and gateway.
The quickstart Docker image installs the controller in its KinD cluster. On other clusters, install the tested version of the controller and its extensions:
kubectl apply --server-side -f https://github.com/kubernetes-sigs/agent-sandbox/releases/download/v1.0.1/sandbox-with-extensions.yaml
kubectl wait --for=condition=Established \
  crd/sandboxes.agents.x-k8s.io \
  crd/sandboxtemplates.extensions.agents.x-k8s.io \
  crd/sandboxwarmpools.extensions.agents.x-k8s.io \
  crd/sandboxclaims.extensions.agents.x-k8s.io --timeout=60s
kubectl create configmap agent-sandbox-config -n agent-sandbox-system \
  --from-literal=allowed-label-domains=sandbox.users.io,archestra.io \
  --dry-run=client -o yaml | kubectl apply -f -
kubectl rollout restart deployment/agent-sandbox-controller -n agent-sandbox-system
kubectl rollout status deployment/agent-sandbox-controller -n agent-sandbox-system --timeout=120s
Give Archestra access to the cluster. When Archestra runs in that cluster, set ARCHESTRA_ORCHESTRATOR_LOAD_KUBECONFIG_FROM_CURRENT_CLUSTER=true. Otherwise, set ARCHESTRA_. Agent Runtime turns on when Archestra finds the controller in the cluster. You do not need to restart Archestra after you install the controller. Check Settings → Agents → Runtimes → Runtime backend. Create an agent with a dedicated runtime and start a run to check image access and storage provisioning.
The controller does not install a container isolation runtime. Check image architecture and admission policies before starting workloads.
| Cluster | What to Check |
|---|---|
| GKE | Linux node pools and the Persistent Disk CSI driver. Autopilot and GKE Sandbox do not allow privileged containers. |
| AKS | Linux agent pools and Azure Disk CSI. Review Pod Security and Azure Policy. |
| EKS with EC2 nodes | The EBS CSI driver with its IAM permissions. |
| EKS Auto Mode | A storage class with ebs.csi.eks.amazonaws.com, and a compatible NodePool. |
| EKS with Fargate | Not supported alone. See EKS With Fargate. |
| Self-managed | A compatible OCI runtime, a CSI driver, and a dynamic storage class. |
Storage and Placement
Runtime workspaces use dynamically provisioned ReadWriteOnce volumes. Set ARCHESTRA_ to your storage class and ARCHESTRA_ to compatible Linux nodes. For zonal disks, use WaitForFirstConsumer and matching node zones. Node-local storage cannot preserve files after node loss.
To keep runs off the node's kernel, use a sandboxed runtime.
Sandboxed Runtime
A run executes code an agent wrote, so give it a kernel of its own. With a sandboxed runtime, each run gets a user-space kernel (gVisor) or a lightweight VM (Kata Containers) instead of sharing the node's kernel, so an escape from the container does not reach the node. Use one in production.
Archestra does not install the runtime. Set it up in the cluster, then point Archestra at its RuntimeClass:
EKS has no managed sandbox. Install gVisor or Kata Containers on a dedicated node group, and create a RuntimeClass for its handler, such as runsc for gVisor. Taint the node group and set the RuntimeClass's scheduling so runs land only on those nodes.
Create a GKE Sandbox node pool with gcloud container node-pools create <pool> --cluster=<cluster> --sandbox=type=gvisor. GKE creates the gvisor RuntimeClass, taints the pool, and adds the matching toleration to every pod that uses it. Autopilot clusters support gvisor with no node pool.
Add an AKS Pod Sandboxing node pool with az aks nodepool add --os-sku AzureLinux --workload-runtime KataVmIsolation. It needs a VM size with nested virtualization. Use the kata-vm-isolation RuntimeClass.
Then set ARCHESTRA_:
archestra:
  env:
    ARCHESTRA_AGENT_RUNTIME_RUNTIME_CLASS_NAME: gvisor
New runs then start on the sandboxed runtime. To check, list the runtime pods in their namespace. Each shows its RuntimeClass. With gVisor, kubectl exec <pod> -- uname -r also reports a different kernel version than the node's:
kubectl get pods -n <namespace> -l archestra.io/agent-workspace \
  -o custom-columns=NAME:.metadata.name,RUNTIME:.spec.runtimeClassName
- Archestra checks that the RuntimeClass exists, at startup and before each run, by asking Kubernetes to admit a test pod as a dry run (nothing is created). If the class is missing, the platform logs an error and runs fail at once with a reason that names it. If the test pod is rejected for another reason, such as an admission policy, Archestra logs that it cannot check and runs start unchecked.
- With
ARCHESTRA_set, give the sandbox nodes that label too.AGENT_ RUNTIME_ NODE_ SELECTOR - Privileged runs ignore the RuntimeClass and share the node's kernel. Keep
ARCHESTRA_off unless runs need Docker.AGENT_ RUNTIME_ ALLOW_ PRIVILEGED
EKS With Fargate
Fargate-only clusters cannot host Agent Runtime's storage. AWS Fargate does not support EBS mounts or dynamic persistent-volume provisioning.
Keep Archestra on Fargate and place runtime containers on EC2 nodes:
- Add an EC2 node group and install the EBS CSI driver with its required IAM permissions.
- Create an EBS storage class with
WaitForFirstConsumerbinding and configure it for runtime workspaces. - Label the nodes, for example
archestra-agent-runtime=true, and use that label in the runtime node selector. - Exclude runtime namespaces and labels from Fargate profiles.
- Install the controller above and start a run.
Runtime Tiers
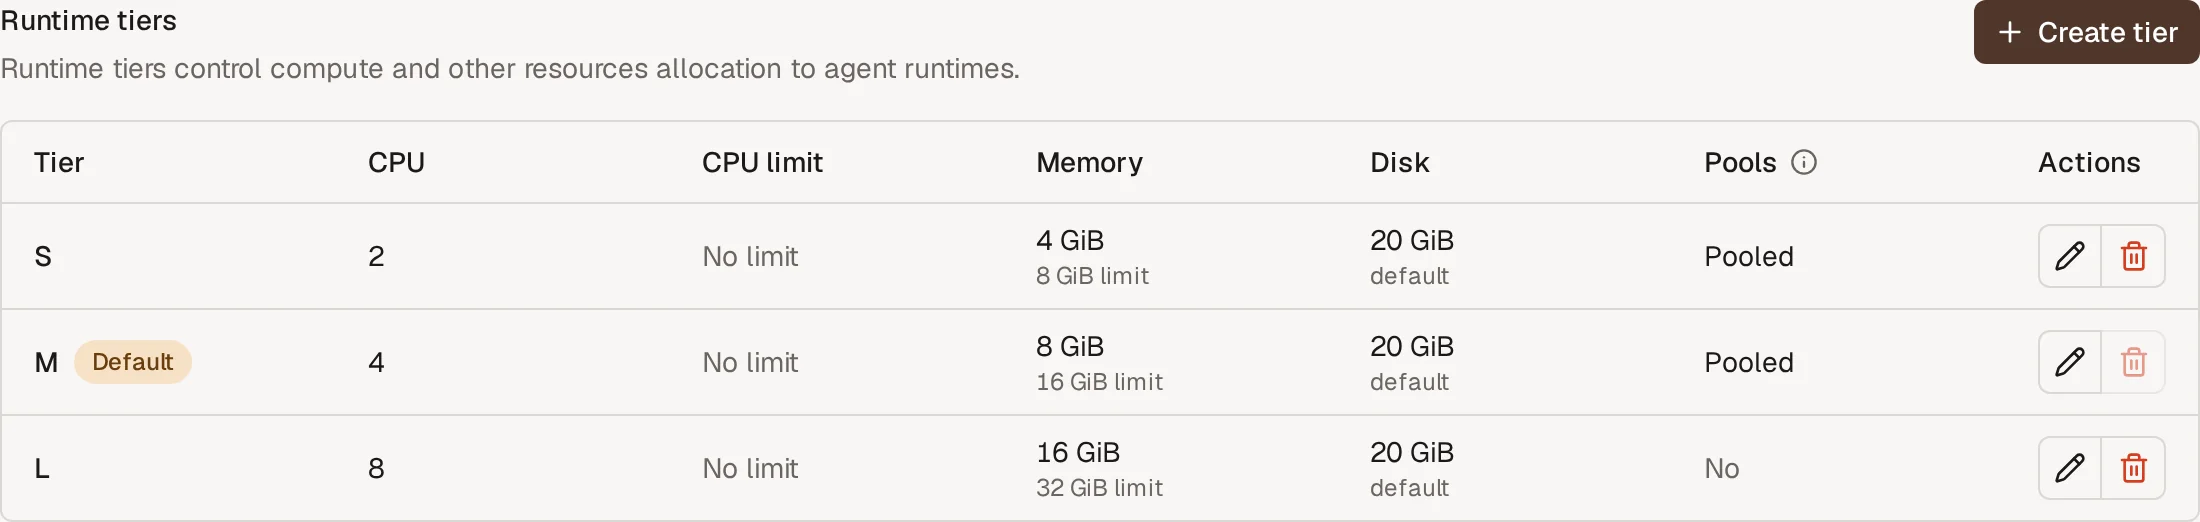
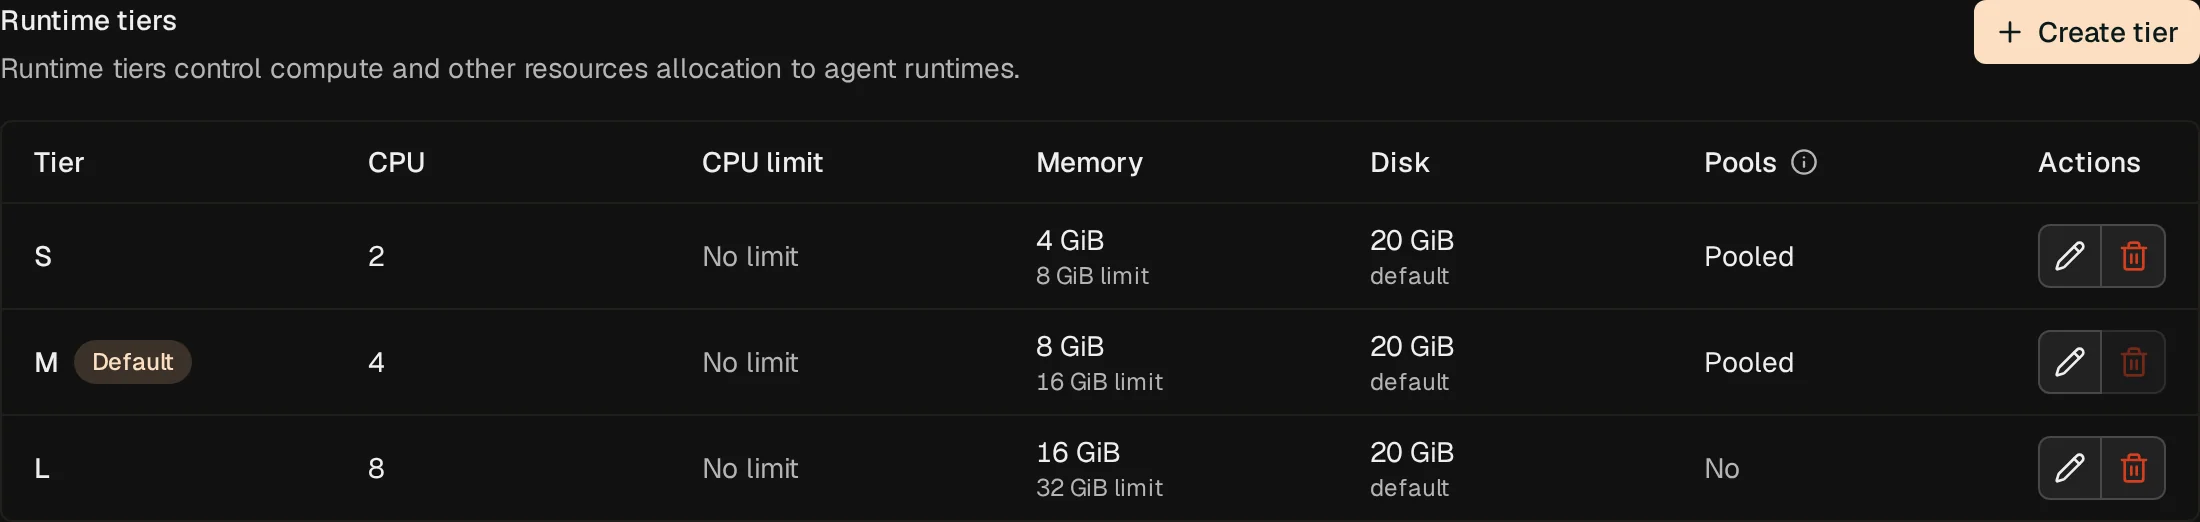
Runtime tiers allocate CPU, memory, and workspace storage to agent runtimes so every run receives predictable resources. Configure your organization's tiers under Settings → Agents → Runtimes → Runtime tiers.
Set Memory request (GiB) and Memory limit (GiB) independently of CPU for memory-heavy workloads. For example, set the CPU request to 0.5 and both memory fields to 8 for an 8 GiB request and limit.
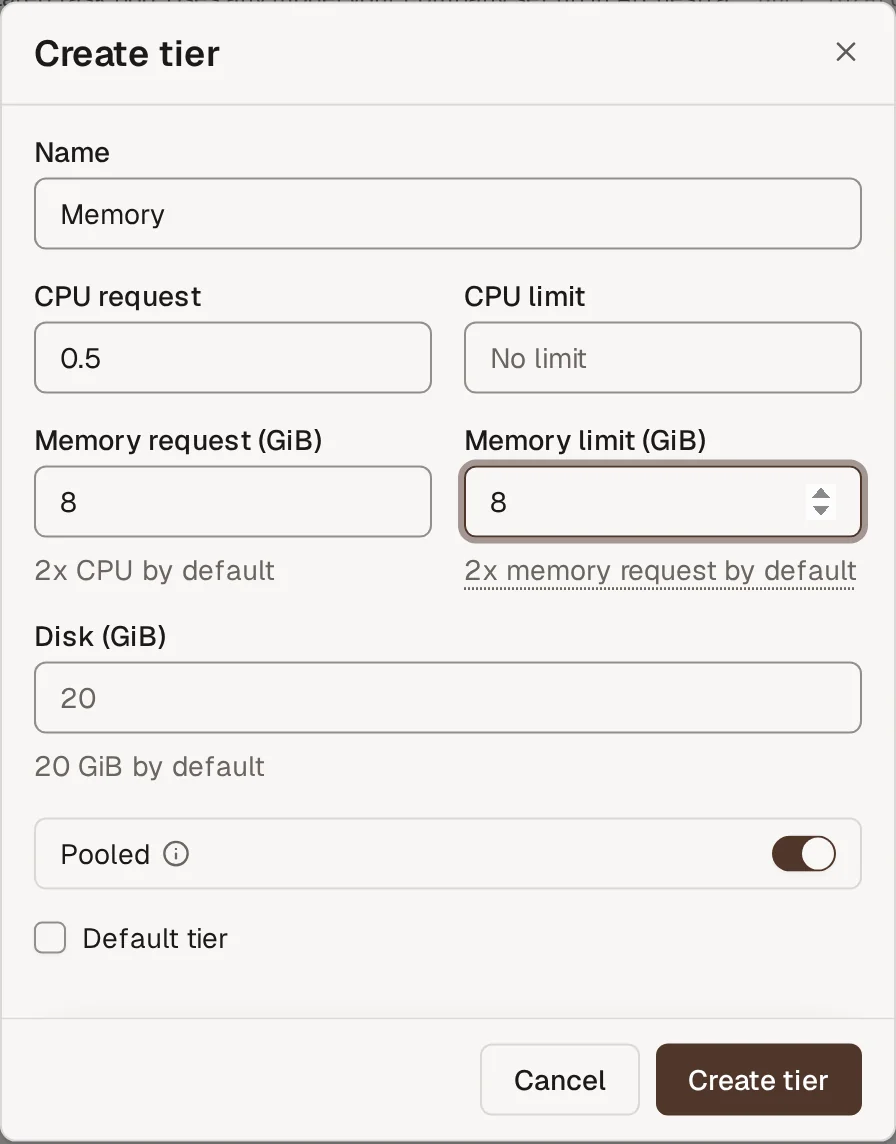
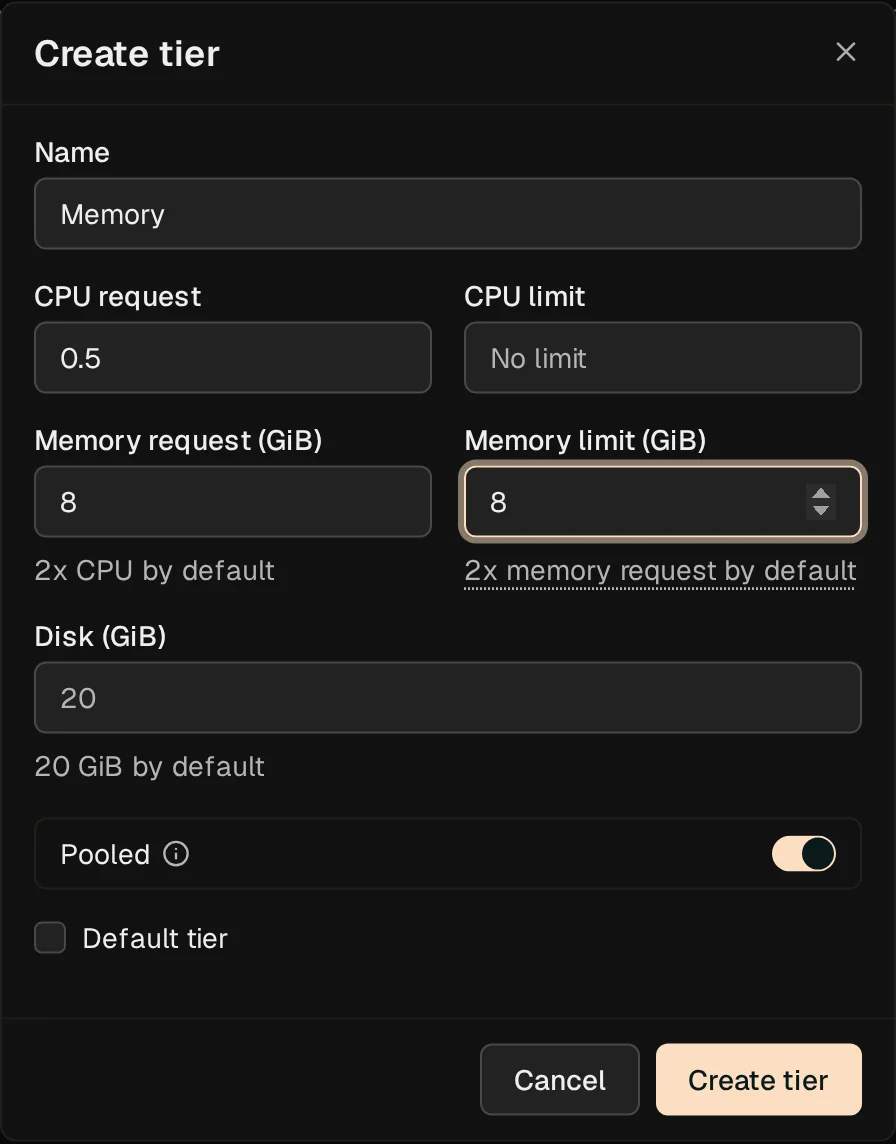
Blank memory fields use defaults in GiB: the request is 2 × CPU request, and the limit is max(2 × memory request, 2 × CPU request, 2 × CPU limit). The limit uses the effective memory request, including an explicit request override. An explicit memory limit overrides that formula. A blank CPU limit leaves CPU uncapped; the memory-limit formula uses the CPU request in its place. A new organization starts with S (2 CPU, 4 GiB), M (4 CPU, 8 GiB), and L (8 CPU, 16 GiB), with M as the default.
Disk sets the size of each run's persistent volume in GiB. The volume holds the run's home directory and, for a privileged agent, its Docker data. A blank size uses ARCHESTRA_. Runs that build container images or run Kubernetes in Docker need about 60 GiB.
Agents do not configure CPU, memory, or storage directly. Each agent selects a Default tier for standard runs and an optional Scaleup tier for larger workloads. Choose Disable autoscaling to disable scaling up. When an agent permits scaling, a run can request any tier up to that scaleup tier.
Pooled tier enables Warm Pool of ready spare agent runtime instances of this tier to eliminate cold starts for new runs. Each spare holds a volume of the tier's workspace size.
Warm Pools
A warm pool keeps spare containers ready, so runs start faster. Agents in the same environment share a pool when their image, resources, storage, placement, and network policy match. Images tagged :latest always start fresh. Spares reserve CPU, memory, and storage, but hold no credentials or network access until a run takes them.
After installing the controller extensions above, set ARCHESTRA_AGENT_RUNTIME_WARM_POOL_SIZE=1 to keep one spare per group. Up to four groups are prepared by default; change this with ARCHESTRA_.
Pools go to the Agents with the most recent runs. Agents with no run in the last 7 days get no spare, so idle Agents don't hold cluster capacity.
Each runtime tier is pooled or not, under Pools in Settings → Agents → Runtimes → Runtime tiers. A pooled tier keeps ARCHESTRA_ spares per group; a tier that is not pooled starts every run in a new container. A new organization pools S and M but not L: a large run is rare and an idle spare holds its full size.
Assigned containers never return to the pool. Without a spare, a run starts a new container. Setting the size to 0 removes unused spares and preserves assigned runs.
Archestra maintains the configured pool replica count. An HPA targeting these pools would compete with Archestra; use node autoscaling to grow cluster capacity as runtime demand increases.
Privileged Containers
Ordinary coding agents do not need privilege. Docker-in-Docker and nested Kubernetes workloads may need it. Set ARCHESTRA_AGENT_RUNTIME_ALLOW_PRIVILEGED=true, enable elevated permissions on the agent, and use nodes whose runtime and admission policy permit privileged containers. Use a dedicated namespace, and put privileged runs on their own tainted node pool with ARCHESTRA_.
Privileged runs ignore the sandboxed runtime. After resuming a run, restart Docker and development services. The deployment setting does not override cloud-provider restrictions.
Runtime Image Cache
Archestra prefetches maintained catalog images onto runtime nodes. Registry and tag settings follow ARCHESTRA_ and ARCHESTRA_. Custom images download when a run starts.
Prefetch uses the runtime namespace's default ServiceAccount image pull secrets. Each image consumes disk on every matching node. Fresh nodes still need their first download; an unavailable image does not block other launches.
Upgrades
Upgrading Archestra moves every agent made from a catalog template onto the new maintained image. You do not edit agents after an upgrade. An agent runs this deployment's image, whatever tag was current when someone created it.
- New runs start on the new image.
- Retained workspaces move to the new image on their next turn. Archestra restarts the workspace and keeps its files and conversation.
- A turn already running keeps its image until it ends.
A custom image, or a maintained image you pinned by digest alone (…/agent-codex@sha256:…, no tag), runs exactly as saved.
Troubleshooting
When runs do not start:
- Runtime unavailable: check Settings → Agents → Runtimes → Runtime backend, and confirm the Agent Sandbox controller is healthy.
- Run waits on storage: check the storage class and its capacity.
- Image pull fails: check the image name, registry access, and pull credentials.
Chat shows the reported startup error.
Scheduled Runs Keep Getting Skipped
A scheduled task skips a tick while its previous run is unfinished.
- Open the skipped entry in the project's run history. It identifies the blocking run, its elapsed time, and its Maximum duration deadline.
- Click Inspect previous run to inspect it and use Stop if needed.
- Use Maximum duration settings to set the agent's lifetime cap for future runtime sessions. Choose a duration long enough for healthy work to finish.
- Changing the cap does not shorten an existing run's deadline. Skipped entries preserve the deadline and elapsed time recorded at that tick.
- A queued run gets its runtime deadline after launch. Foreground chat runs do not use the runtime lifetime cap.
- After a run stops or reaches its deadline, the schedule waits for workload cleanup before starting another run.